Publications
Eeshaan Jain, Linus Bleistein, Bart Deplancke, Charlotte Bunne
The Fortieth Annual Conference on Neural Information Processing Systems (NeurIPS 2026)
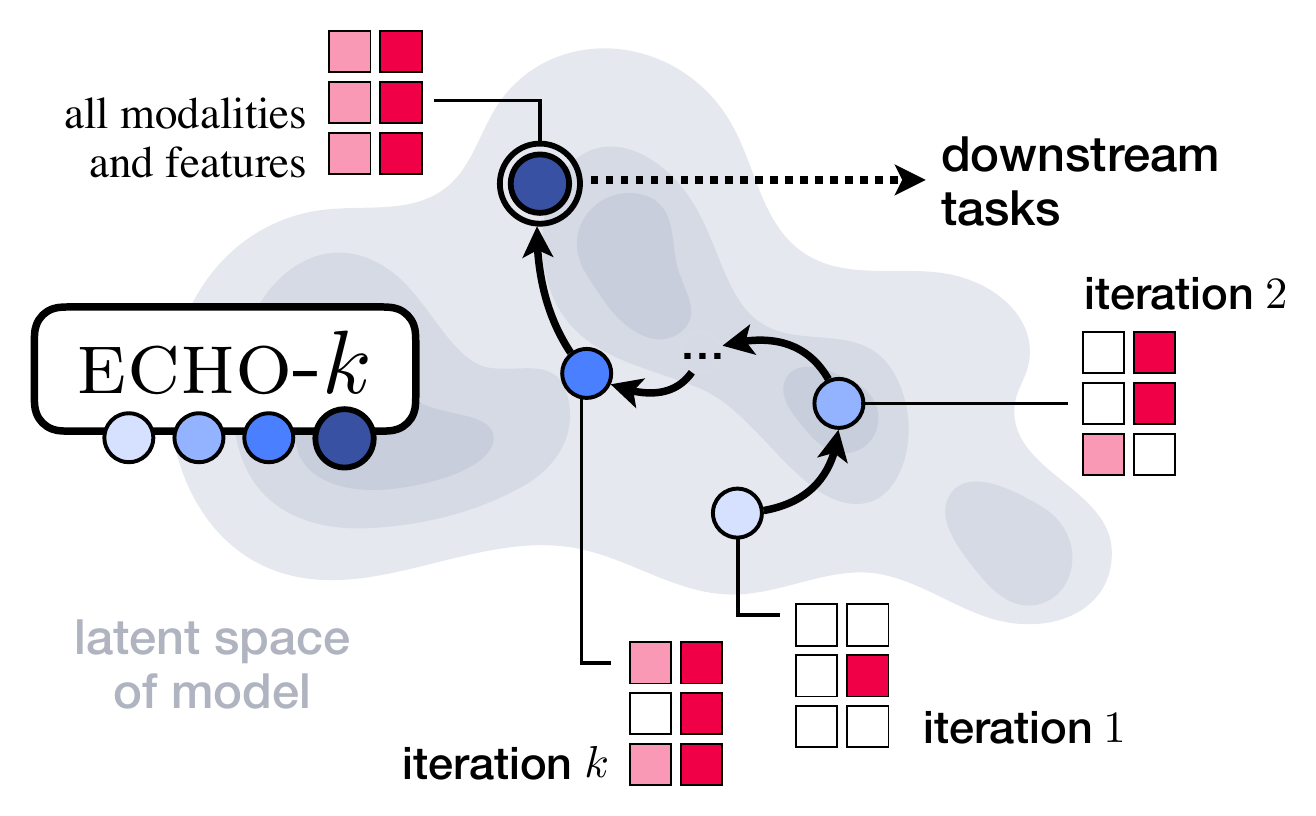
Recent progress in multimodal, high-dimensional learning has enabled foundation models to process heterogeneous, large-scale data. However, at test time, acquiring all features or modalities can be prohibitively costly and often redundant. Sequentially selecting informative modalities is therefore critical, yet challenging when the downstream task or prediction target is unknown. To this end, we introduce ECHO-k, a task-agnostic and self-supervised learning principle for modality acquisition: we use a deep model’s internal pretrained representations (e.g., from a foundation model) as proxy targets that summarize cross-modal information. We provide theoretical guarantees in a linear model setting that motivate a reinforcement learning (RL) policy for sequential modality selection. Across benchmarks, the resulting acquisition strategies transfer reliably and achieve state-of-the-art performance on downstream tasks that are entirely unseen during selection. Our method provides a principled route to cost-aware test-time deployment, with implications for any multimodal system where measurements are expensive or time-constrained, and downstream tasks unknown a priori.
Show BibTeX
Benedikt von Querfurth*, Eeshaan Jain*, Johann Wenckstern*, Lukas Klein*, Phil F Cheng, Yexiang Cheng, Cédric Vincent-Cuaz, Pascal Frossard, Martina Haberecker, Andreas Wicki, Olivier Michielin, Charlotte Bunne
The Fortieth Annual Conference on Neural Information Processing Systems (NeurIPS 2026), Evaluations & Datasets Track
Spatial proteomics (SP) captures the molecular composition and spatial organization of tissues at single-cell resolution, opening a direct view of the cellular ecosystems that drive disease. Protein panels, acquisition platforms, and tissue contexts differ from one cohort to the next, and a coherent picture of tissue biology can only emerge from models trained to bridge this heterogeneity. Foundation models offer the natural path forward, but their training depends on large, harmonized corpora that span platforms, panels, and cohorts. No public resource currently approaches that scale; available data sit in small, narrowly scoped releases with incompatible formats and conventions. We present spora, a large-scale multimodal SP dataset of 12,596 standardized multiplex images from 5,254 patients across 31 cohorts and four major SP technologies. Curated with biomedical experts, spora provides model-training-ready formats together with cell and tissue segmentations, structured clinical metadata, and, where available, paired H&E enabling the training of virtual staining models. It is complemented by spora [io], a unified interface for tiling, sampling, and standardization across all cohorts and modalities, and spora [bench], a benchmark suite spanning cell- and patient-level tasks across 11 cohorts that places current SP foundation models on common ground against task-specific baselines for the first time.
Show BibTeX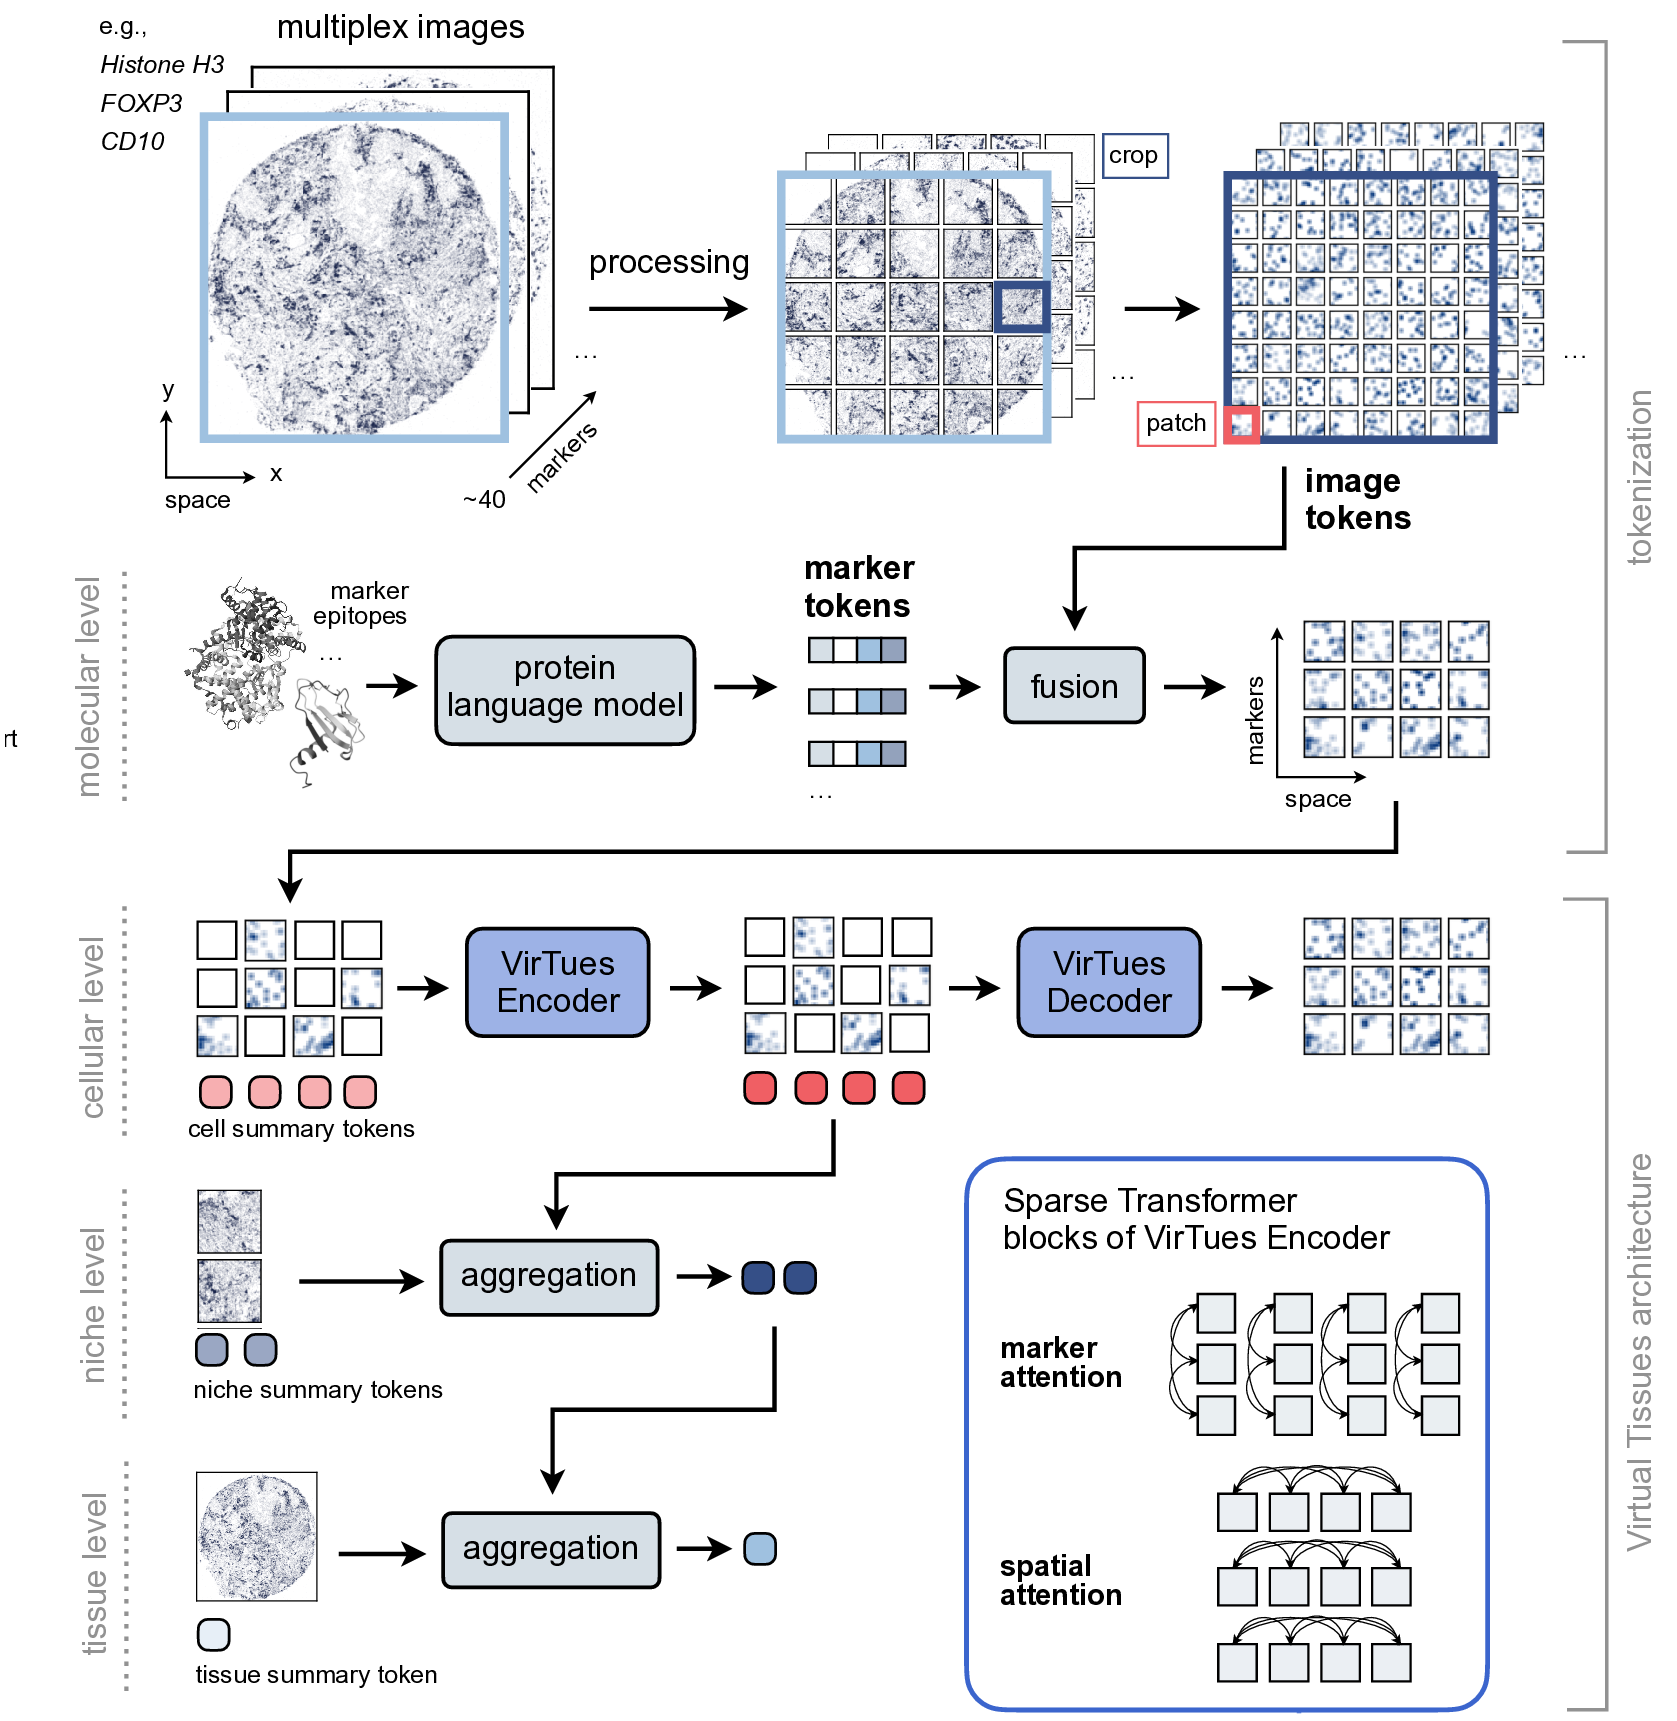
Johann Wenckstern*, Eeshaan Jain*, Benedikt von Querfurth, Yexiang Cheng, Kiril Vasilev, Matteo Pariset, Phil F. Cheng, Petros Liakopoulos, Olivier Michielin, Andreas Wicki, Gabriele Gut, Charlotte Bunne
Nature (2026)
Spatial proteomics technologies have transformed our understanding of complex tissue architectures by enabling simultaneous analysis of multiple molecular markers and their spatial organization. The high dimensionality of these data, varying marker combinations across experiments and heterogeneous study designs pose unique challenges for computational analysis. Here, we present Virtual Tissues (VirTues), a foundation model framework for biological tissues that operates across the molecular, cellular and tissue scale. VirTues introduces innovations in transformer architecture design, including a novel tokenization scheme that captures both spatial and marker dimensions, and attention mechanisms that scale to high-dimensional multiplex data while maintaining interpretability. Trained on diverse cancer and non-cancer tissue datasets, VirTues demonstrates strong generalization capabilities without task-specific fine-tuning, enabling cross-study analysis and novel marker integration. As a generalist model, VirTues outperforms existing approaches across clinical diagnostics, biological discovery and patient case retrieval tasks, while providing insights into tissue function and disease mechanisms.
Show BibTeX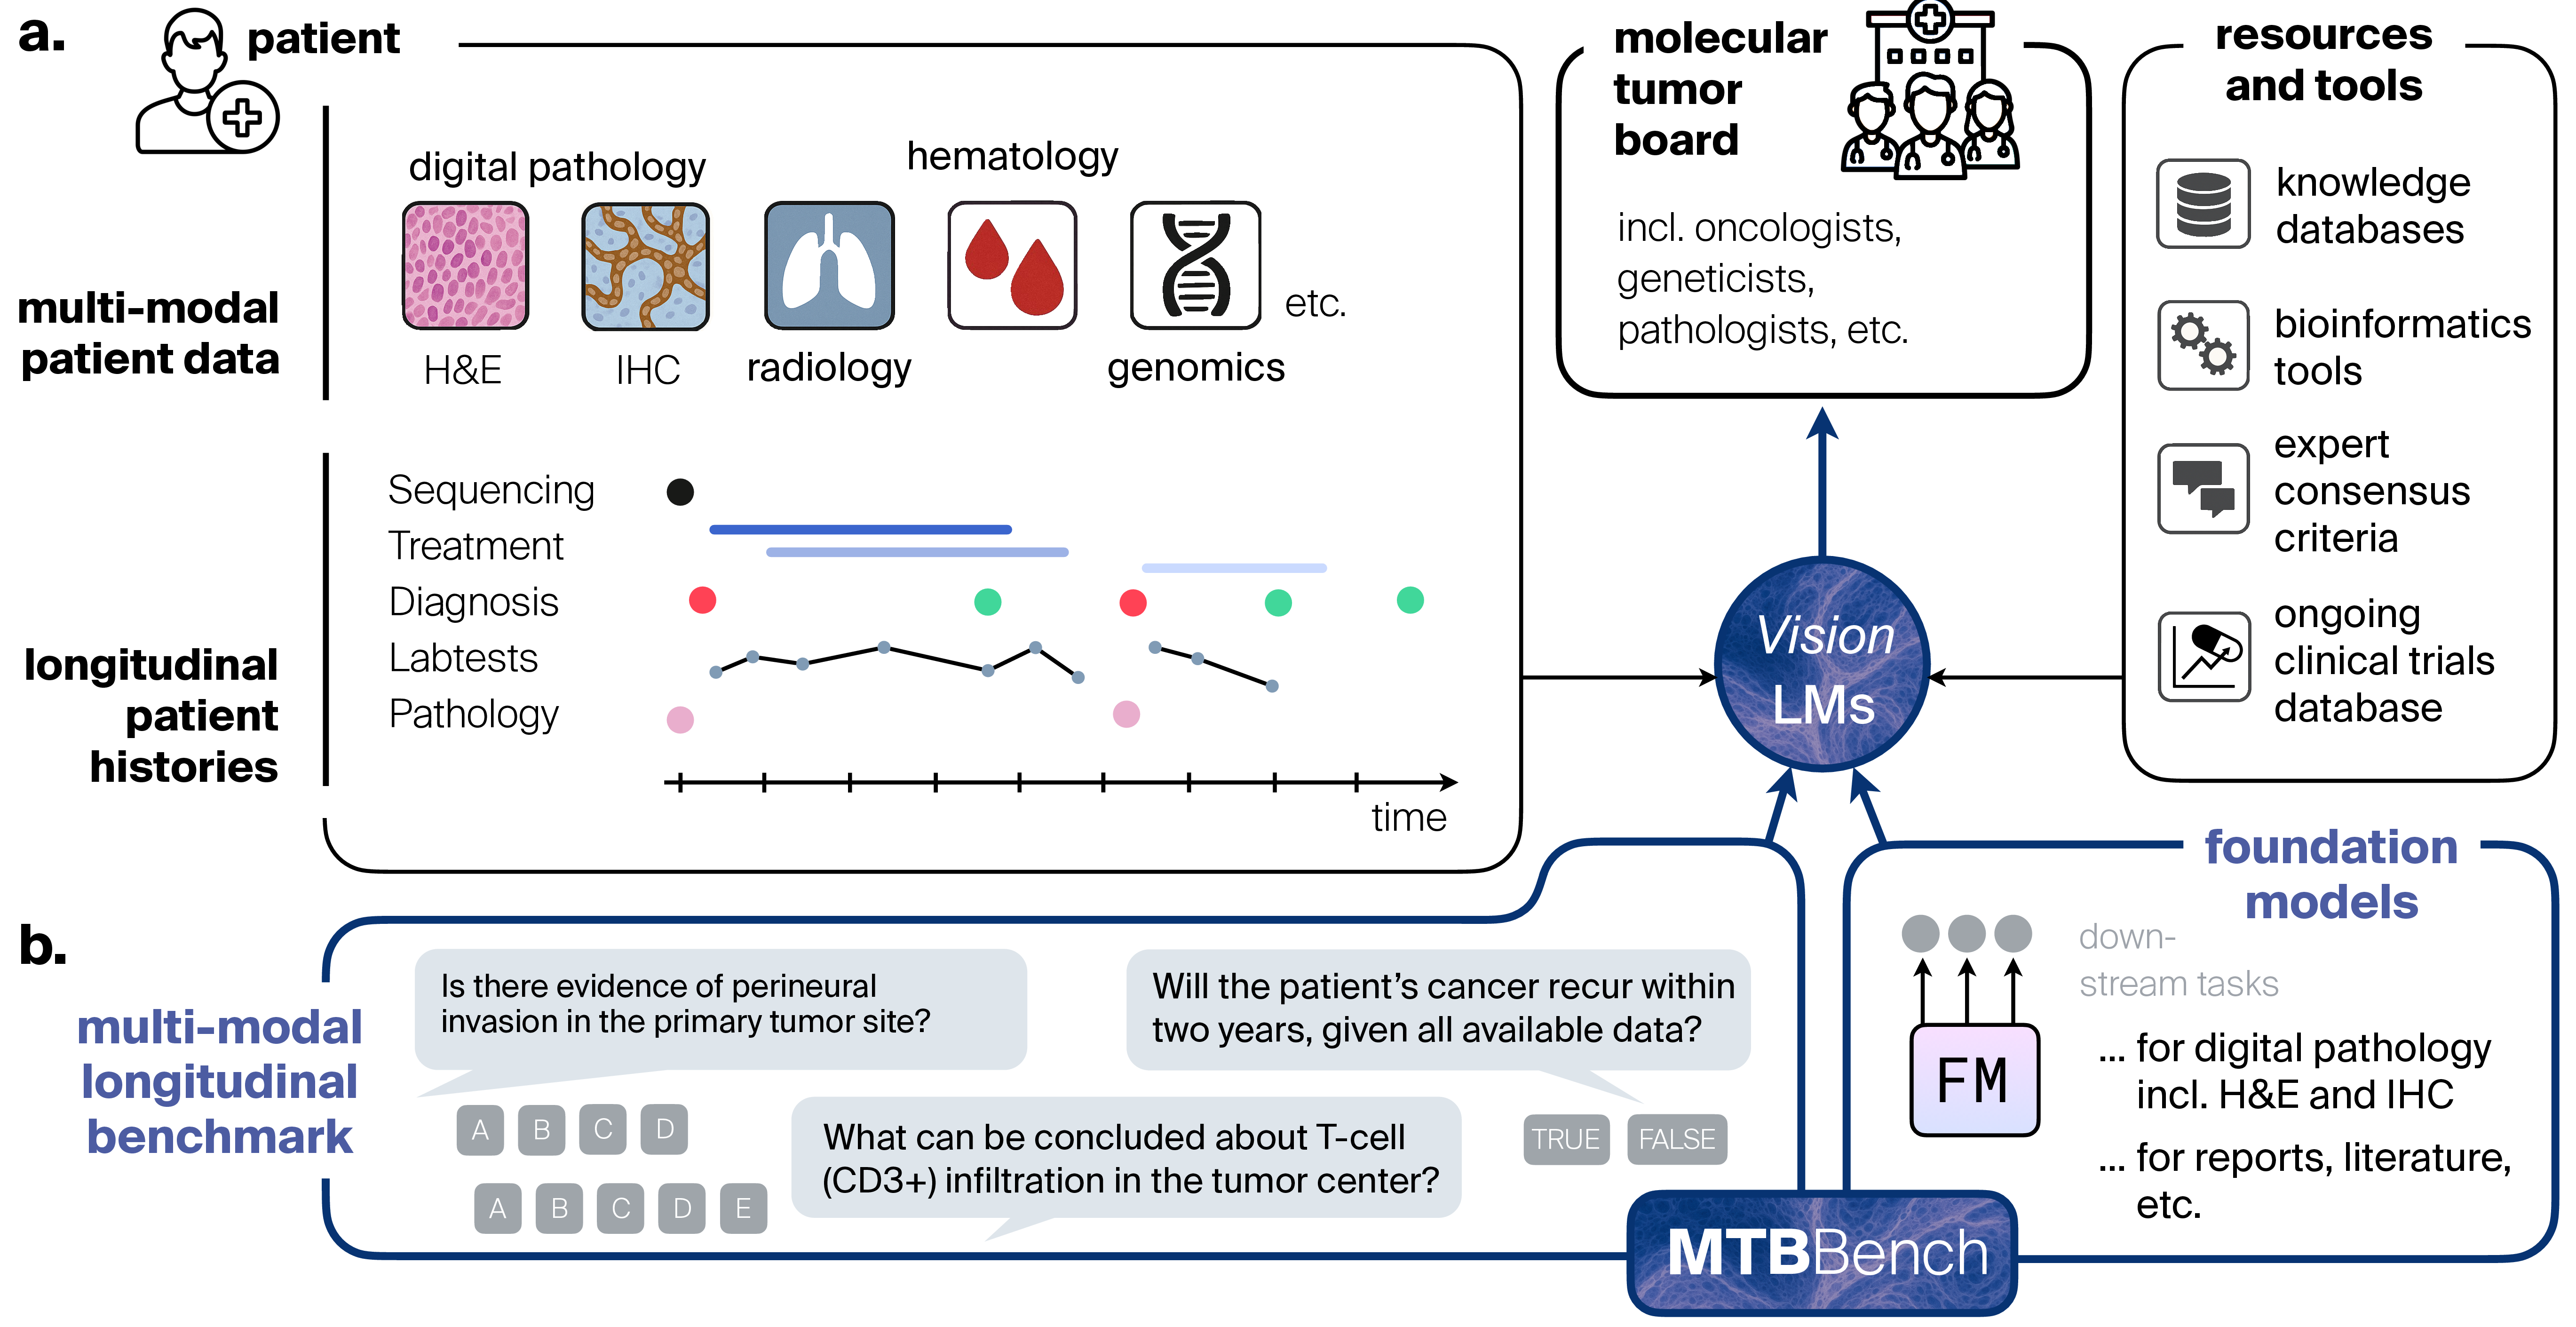
Eeshaan Jain*, Kiril Vasilev*, Alexandre Misrahi*, Phil F Cheng, Petros Liakopoulos, Olivier Michielin, Michael Moor , Charlotte Bunne
The Thirty-eighth Annual Conference on Neural Information Processing Systems (NeurIPS 2025)
Multimodal Large Language Models (LLMs) hold promise for biomedical reasoning, but current benchmarks fail to capture the complexity of real-world clinical workflows. Existing evaluations primarily assess unimodal, decontextualized question-answering, overlooking multi-agent decision-making environments such as Molecular Tumor Boards (MTBs). MTBs bring together diverse experts in oncology, where diagnostic and prognostic tasks require integrating heterogeneous data and evolving insights over time. Current benchmarks lack this longitudinal and multimodal complexity. We introduce MTBBench, an agentic benchmark simulating MTB-style decision-making through clinically challenging, multimodal, and longitudinal oncology questions. Ground truth annotations are validated by clinicians via a co-developed app, ensuring clinical relevance. We benchmark multiple open and closed-source LLMs and show that, even at scale, they lack reliability---frequently hallucinating, struggling with reasoning from time-resolved data, and failing to reconcile conflicting evidence or different modalities. To address these limitations, MTBBench goes beyond benchmarking by providing an agentic framework with foundation model-based tools that enhance multi-modal and longitudinal reasoning, leading to task-level performance gains of up to 9.0% and 11.2%, respectively. Overall, MTBBench offers a challenging and realistic testbed for advancing multimodal LLM reasoning, reliability, and tool-use with a focus on MTB environments in precision oncology.
Show BibTeX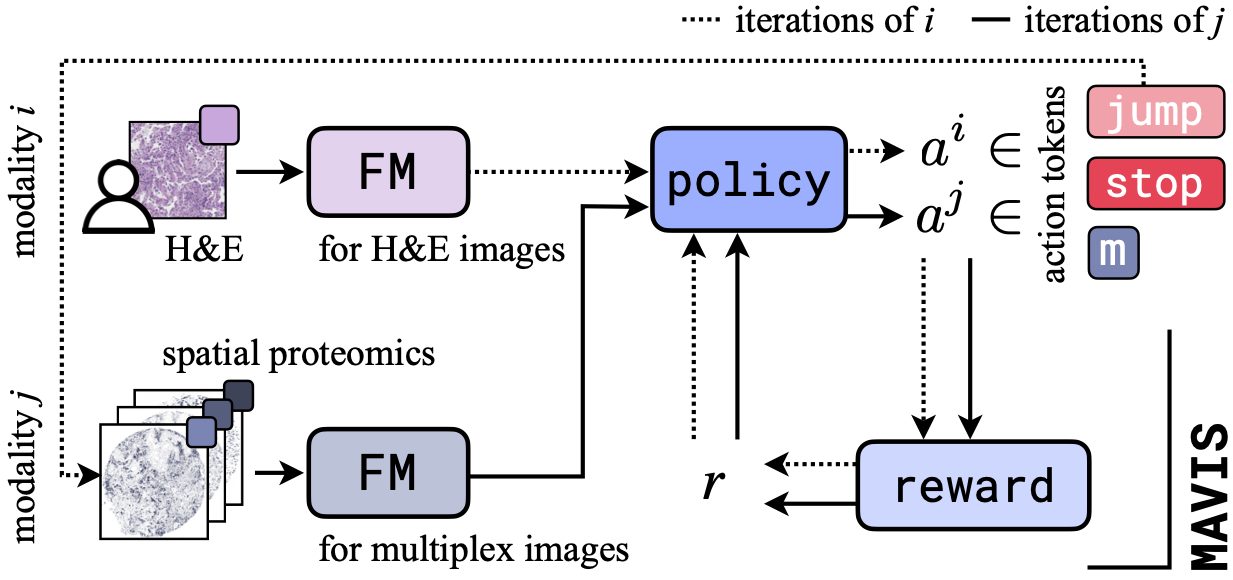
Eeshaan Jain, Johann Wenckstern, Benedikt von Querfurth, Charlotte Bunne
Oral (Top 4%) @ MLGenX Workshop & Poster @ GemBio Workshop, ICLR 2025
The clinical routine has access to an ever-expanding repertoire of diagnostic tests, ranging from routine imaging to sophisticated molecular profiling technologies. Foundation models have recently emerged as powerful tools for extracting and integrating diagnostic information from these diverse clinical tests, advancing the idea of comprehensive patient digital twins. However, it remains unclear how to select and design tests that ensure foundation models can extract the necessary information for accurate diagnosis. We introduce MAVIS (Multi-modal Active VIew Selection), a reinforcement learning framework that unifies modality selection and feature selection into a single decision process. By leveraging foundation models, MAVIS dynamically determines which diagnostic tests to perform and in what sequence, adapting to individual patient characteristics. Experiments on real-world datasets across multiple clinical tasks demonstrate that MAVIS outperforms conventional approaches in both diagnostic accuracy and uncertainty reduction, while reducing testing costs by over 80%, suggesting a promising direction for optimizing clinical workflows through intelligent test design and selection.
Show BibTeX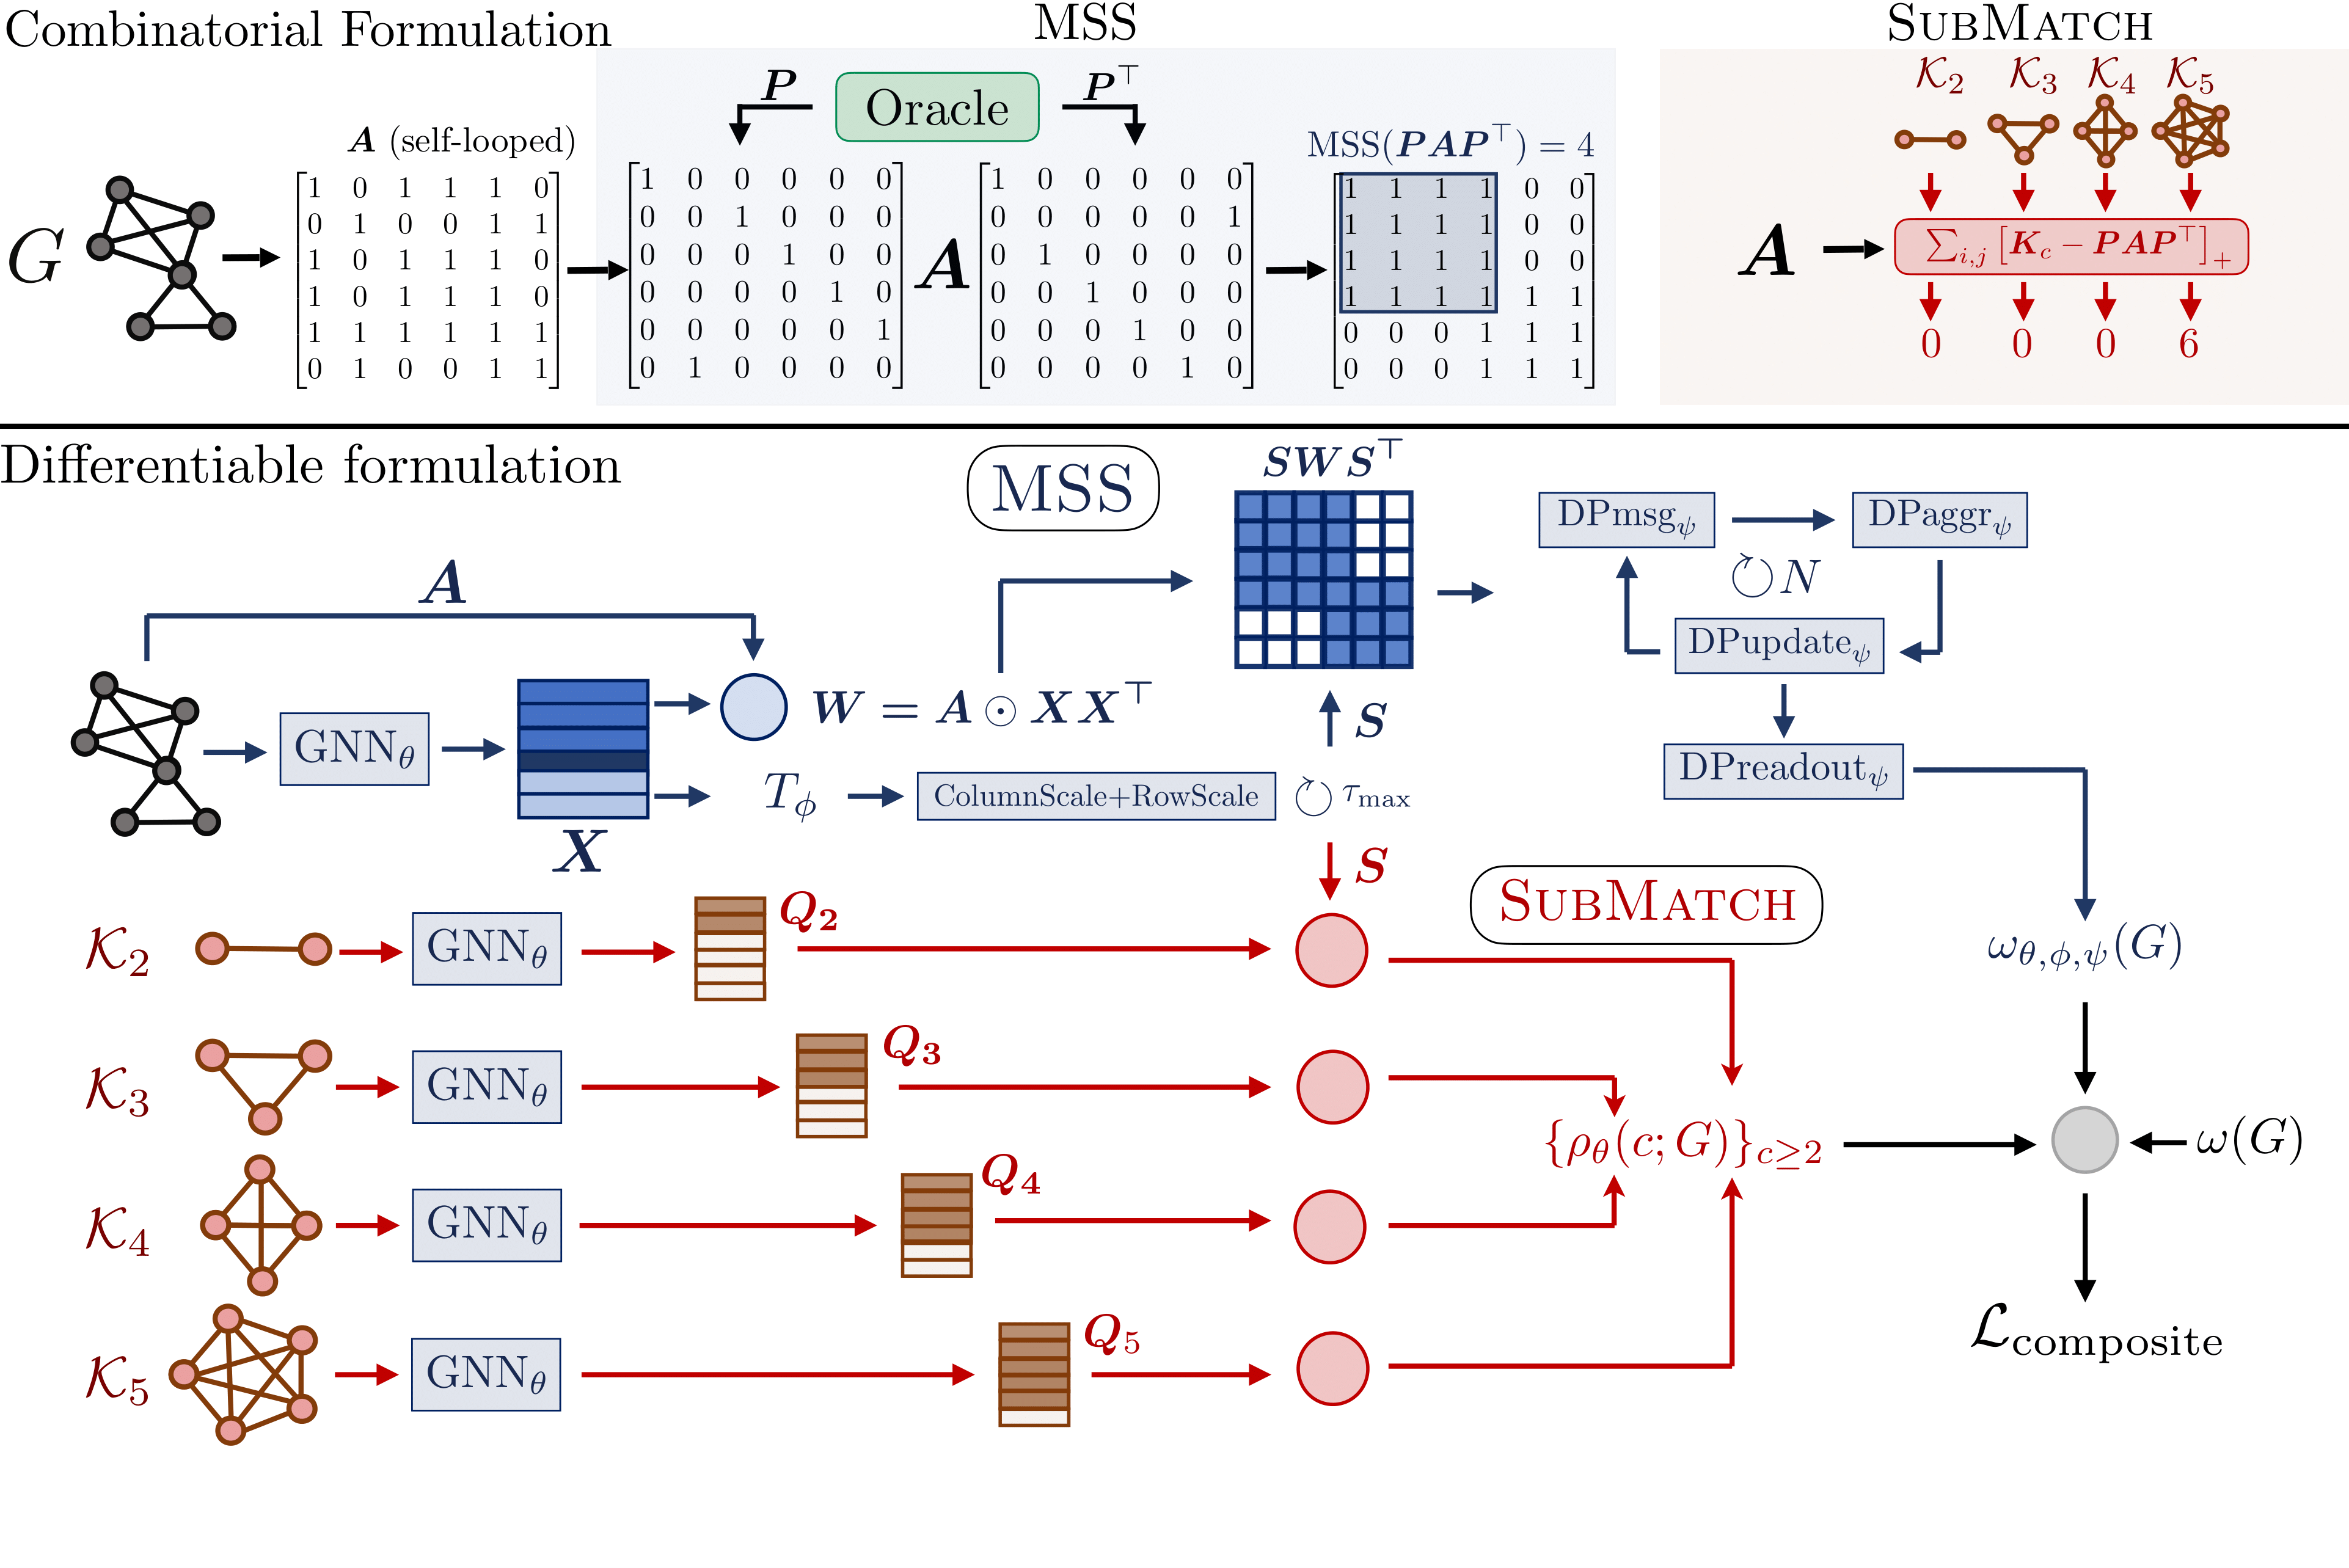
Indradyumna Roy*, Eeshaan Jain*, Soumen Chakrabarti, Abir De
ICLR 2025
MxNet is a fully differentiable clique number estimator that learns from distant supervision without explicit clique demonstrations. We reformulate MCP as detecting dense submatrices via learned permutations within a nested subgraph matching task.
Show BibTeX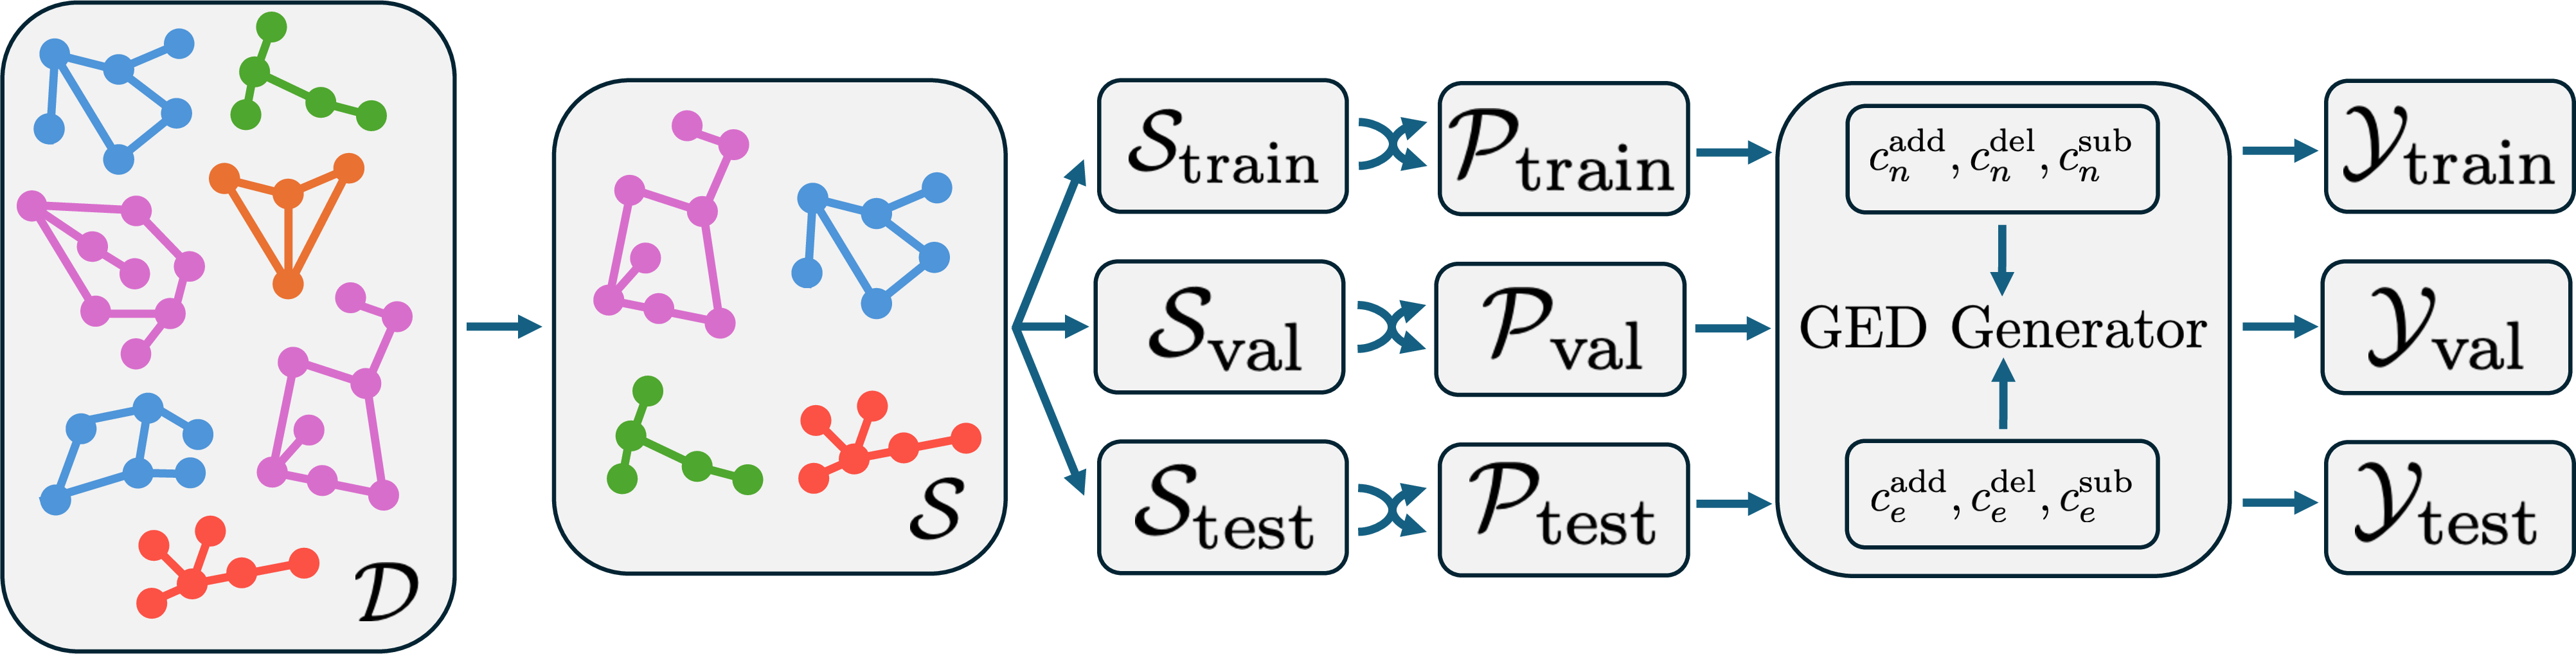
Eeshaan Jain*, Indradyumna Roy*, Saswat Meher, Soumen Chakrabarti, Abir De
LoG 2024 (Extended Abstract)
Graph Edit Distance (GED) is a powerful framework for modeling both symmetric and asymmetric relationships between graph pairs under various cost settings. Due to the combinatorial intractability of exact GED computation, recent advancements have focused on neural GED estimators that approximate GED by leveraging data distribution characteristics. However, the datasets commonly used to benchmark such neural models exhibit two critical flaws: (1) significant isomorphism bias and (2) reliance on uniform edit costs for GED ground truths. Our datasets eliminate isomorphism leakage and incorporate a range of edit costs, facilitating more accurate assessment of GED methods.
Show BibTeX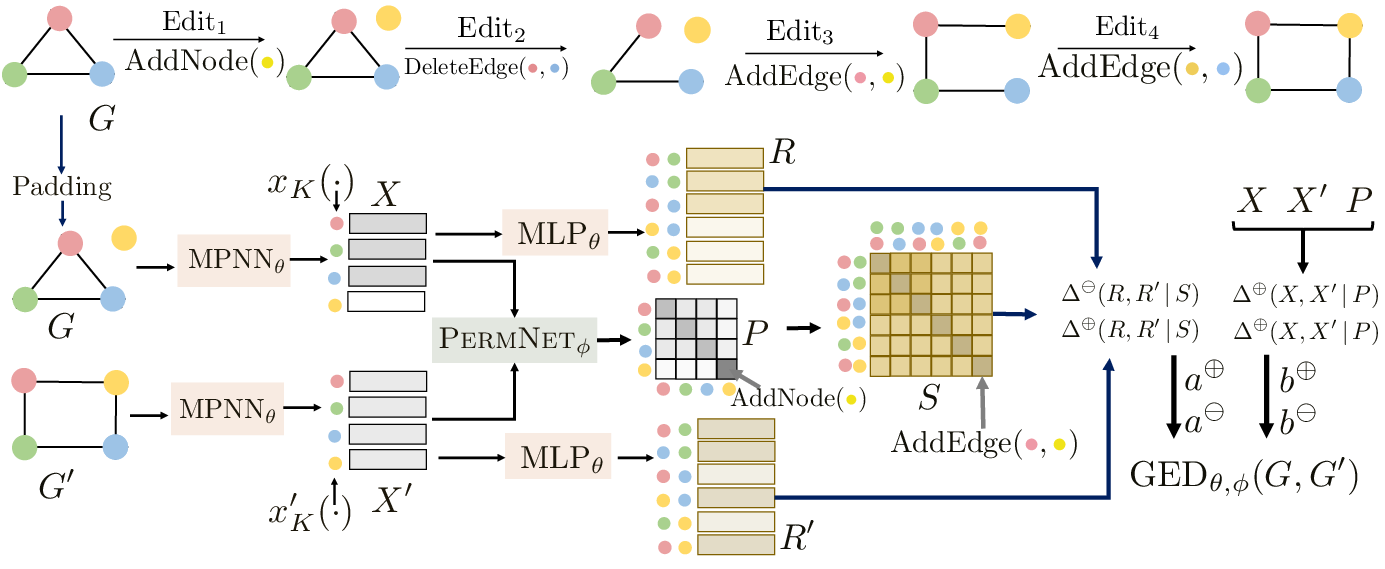
Eeshaan Jain*, Indradyumna Roy*, Saswat Meher, Soumen Chakrabarti, Abir De
NeurIPS 2024 and LoG 2024 (Extended Abstract)
GraphEdx is the first-of-its-kind neural GED framework that incorporates variable edit costs, capable of modeling both symmetric and asymmetric graph (dis)similarities, allowing for more flexible and accurate GED estimation compared to earlier methods.
Show BibTeX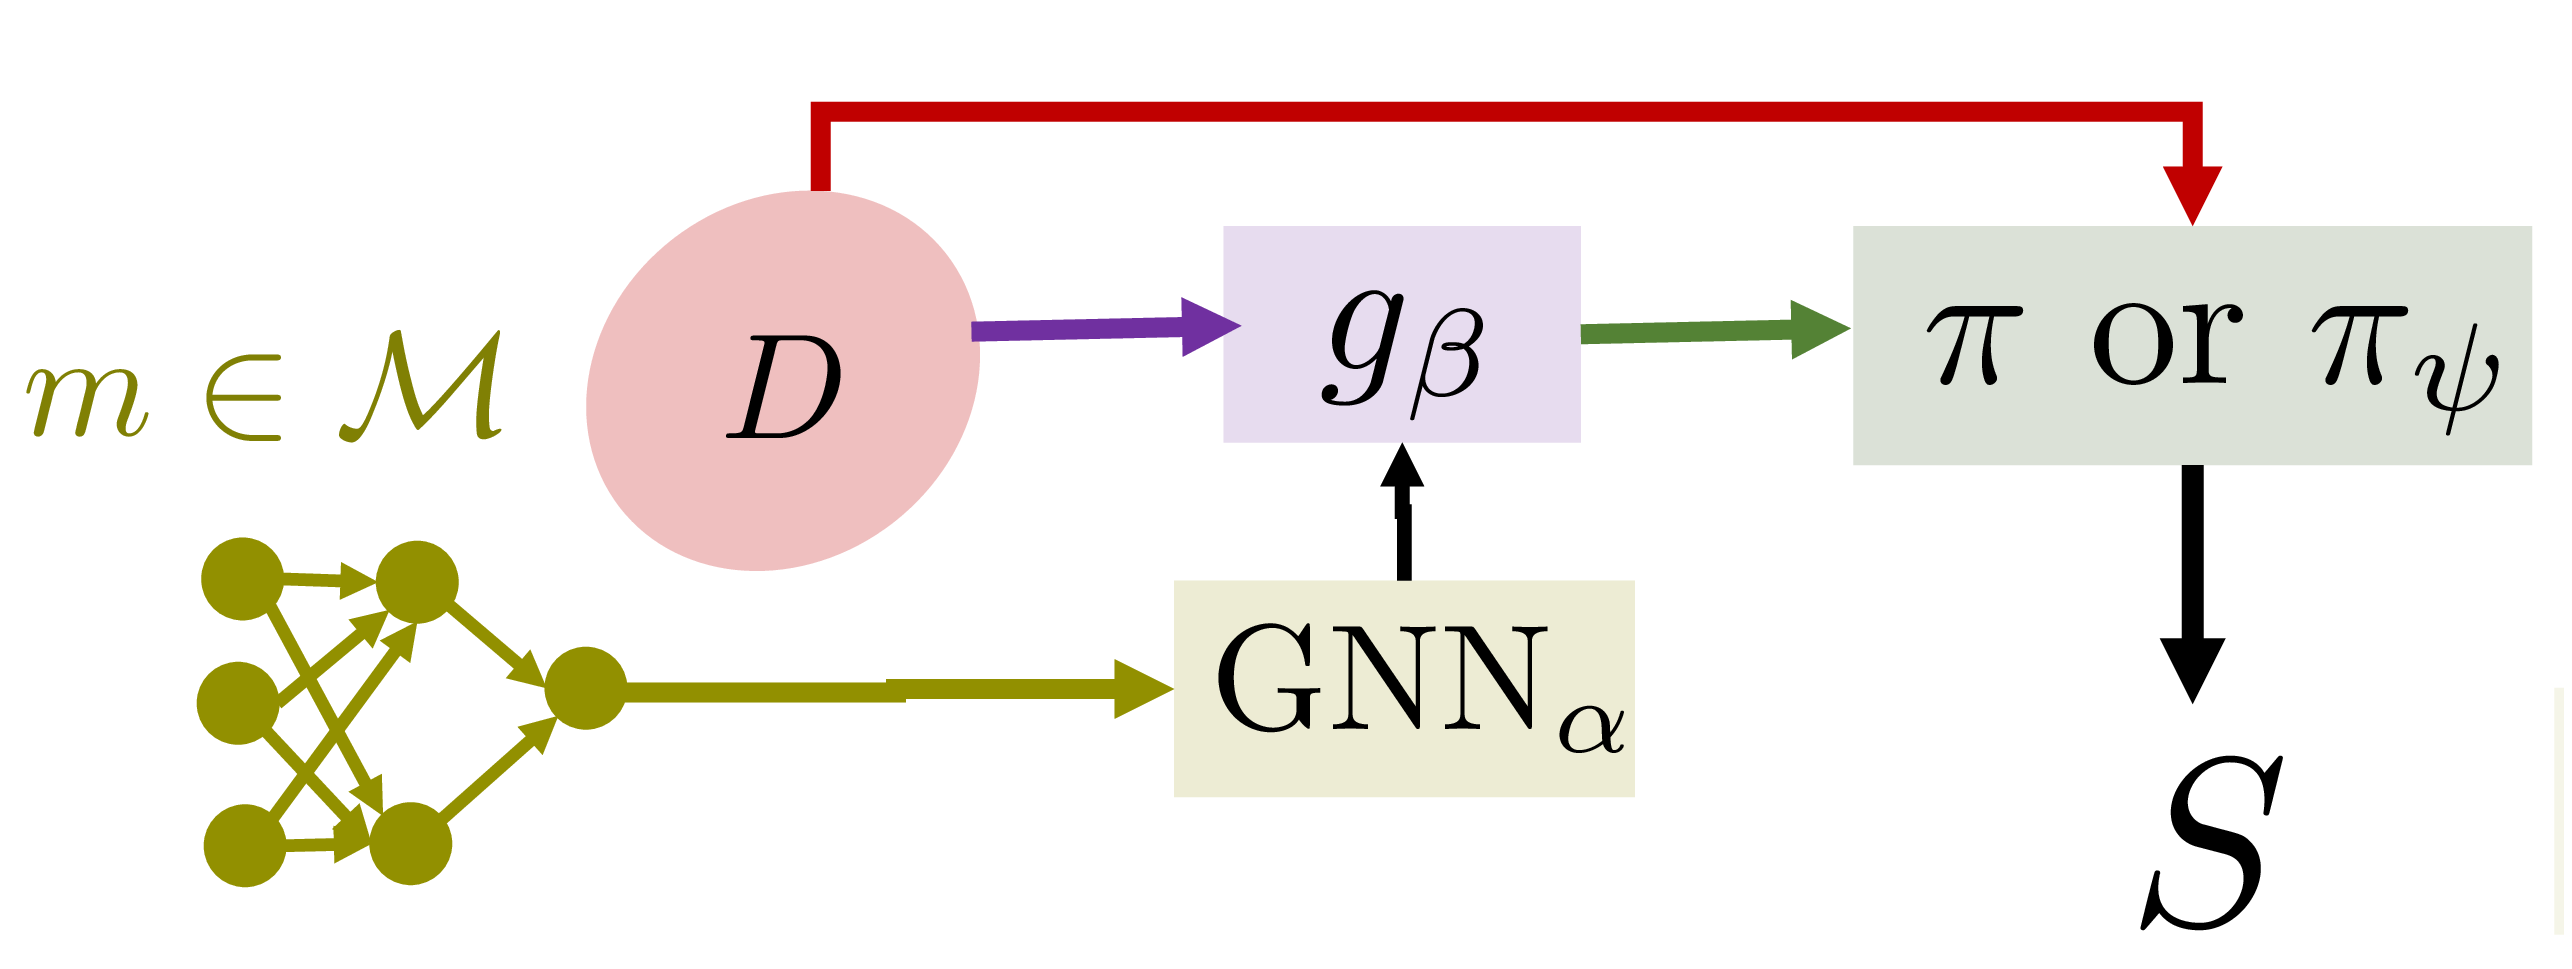
Eeshaan Jain, Tushar Nandy, Gaurav Aggarwal, Ashish V. Tendulkar, Rishabh K Iyer, Abir De
NeurIPS 2023
Existing subset selection methods for efficient learning predominantly employ discrete combinatorial and model-specific approaches, which lack generalizability--- for each new model, the algorithm has to be executed from the beginning. We propose `SubSelNet`, a non-adaptive subset selection framework, which tackles these problems.
Show BibTeX